 siftwise blog
Release · v0.1.0
Introducing siftwise: run only the tests your change needs, safely
Coding agents write pull requests faster than CI can test them. siftwise is a self-hosted service that picks the tests a change can affect, runs the full suite whenever it isn't sure, and tells people and agents whether each failure is a new regression, already broken on main, or flaky. Version 0.1.0 is out today on PyPI and GHCR. Here's how it works, how to try it, and what replays of four real repos' CI history do and don't show.
The problem: CI is the bottleneck#
Coding agents made writing a change cheap. Verifying it didn't get any cheaper. Anthropic reports a 25x increase in CI jobs over six months as agents sped up writing code (Agentic coding is straining CI), and Linear found that as development accelerates, CI becomes a bottleneck, because every PR still has to pass through it (AI coding has made CI a bottleneck).
Most pipelines answer "which tests does this change need?" with "all of them". That is safe, and on a large suite it is slow: every push pays for tests the change can't reach. And when something fails, someone still has to work out whether the change broke it, main was already broken, or the test is flaky. An agent that can't tell those apart may spend its next turn "fixing" a failure it didn't cause.
Why existing approaches fall short#
Test selection isn't new, and good tools exist. Going by each project's public docs as of October 2026 (corrections welcome):
- Coverage-based selection (Datadog Test Impact Analysis, pytest-testmon) records which tests execute which code. That sees dynamic dependencies a static graph misses, but needs instrumented runs; Datadog's is SaaS, and testmon is a local plugin with no server.
- Predictive selection (Develocity Predictive Test Selection, CloudBees Smart Tests) learns from past builds. Develocity is self-hosted but built for Gradle and Maven; neither is open source.
- Path filters are cheap and risky. On kubo, mapping changed files to tests by name caught 1 of 9 failures with the fallbacks switched off: the failures were in packages that depend on the change.
At the time of writing, I didn't find agent or MCP support documented for these tools. That gap, plus self-hosting with no instrumentation, is where siftwise sits.
What siftwise is#
siftwise is self-hosted test selection plus failure triage, for CI and for coding agents. It records every CI test result in your own Postgres, with no test instrumentation; selects the tests a change can affect, each with a reason; gives each failure a verdict with its evidence; and measures its own misses in shadow mode. Apache-2.0.
It ships as a light CLI (pip install siftwise), three GitHub composite actions,
an MCP server (siftwise mcp), and an API server published as a Docker image.
Import graphs are computed by the client, in the checkout, so the server never needs your
source code.
It fails open. An unreachable server, a timeout, an HTTP error or a
missing token makes select run the full suite and record/rollup
log a warning. A siftwise outage never blocks CI. The one exception is fail-on,
which you opt into, and which then fails closed, so an outage can't let a regression
through.
How it works#
flowchart TD
    A["PR or agent branch"] --> B["select: git diff + import graphs"]
    B --> C["run: selected tests, or the full suite"]
    C --> D["record: JUnit per matrix leg"]
    D --> E["rollup: per-test history"]
    E --> F["triage: a verdict per failure"]
    F --> G["shadow compare: caught or missed"]
    G --> H["sticky PR comment"]
    DB[("Postgres
per-test history")]
    B <-.-> DB
    D -.-> DB
    F <-.-> DB
- Select. The client sends the changed files and what they link to; the
server returns a
mode(selectiveorfull), each selected test with its reasons, and a ready-to-run command. - Run. CI runs that command, or its full suite when the mode is
full. - Record. One idempotent JUnit upload per matrix leg.
- Rollup. Per-test history is recomputed over a 90-day window, once per CI run, after every leg.
- Triage. Every failing test gets a verdict from history before the run.
- Shadow compare. On a shadow run, each failure is checked against the stored selection: caught, missed (with a cause), or flaky (counted apart).
Selection signals#
- Path mapping:
foo.py→test_foo.py, Go package directories, JS/TS test files. - Import graphs: Go via
go list -deps -test; Python via a static graph including parent packages, conftests and module names in strings. - Co-change from past failing runs, and tests recently failing on main.
- Declared dependencies no import graph can see, as
[[depends]]rules in.siftwise.toml, plusalways_runglobs.
always_run = ["tests/smoke/**", "tests.test_health::*"]  # test file paths or test IDs
known_flaky = ["tests/test_net.py"]       # triage: unlinked failures are flaky

[[depends]]                               # dependencies no import graph can see
tests = "test/cli/**"                     # test file paths, or <Go package dir>/<TestName>
on = ["**/*.go", "!**/*_test.go"]         # ! excludes
A changed or imported test file runs whole, and a changed Go package runs without
-run, so tests added by the change run too.
Safe fallbacks#
When unsure, run the full suite: missing a real failure is worse than running extra tests. That covers an unknown or empty diff, no history, a changed root build or CI file, a source file no signal covers, or a selected test with no runner. Docs, lint-only configs and generated files never force it.
Triage verdicts#
Ordered rules decide. A test that passed on the same commit is flaky; one failing on main is pre-existing; one linked to the change, with no flaky evidence, is a new regression; otherwise it's unknown, with low confidence. Triage never guesses and never peeks: only runs before the triaged one count.
new_regression  high   tests.test_cart::test_total
    tests/test_cart.py tests changed src/cart.py
pre_existing    high   tests.test_db::test_query
    failing on main on ubuntu-py3.12 since 4f2a9c1 (3 main runs)
flaky           medium tests.test_net::test_fetch
    flaky 1 time in 90 days (1 unrelated fail-then-pass)
siftwise: 3 failing test(s): 1 new regression, 1 pre existing, 1 flaky, 0 unknown
Use cases#
A team cutting CI time
Add the three actions to your workflow: your test step runs the selected command, or your
normal suite when select says full. Savings depend on structure. In
the Cirq monorepo, PRs touching only cirq-google skipped 79.8% of test time;
PRs in cirq-core, which every other package imports, skipped 20.2%.
A coding agent running only the relevant tests
siftwise mcp gives an agent three tools: select_tests before it runs
tests, triage_failure when tests fail and before it tries to fix them, and
explain when a selection or verdict surprises it. Uncommitted work counts,
untracked files included. Results stay under 8,000 characters and never contain the API
token.
Triaging failures: regression, flaky or pre-existing
The sticky PR comment gets a Failures table (test, verdict, confidence,
one reason), new regressions first, never with raw failure messages. To gate on it, set
fail-on: new_regression,unknown. Known flakes go in known_flaky; for a
PR the base commit's list applies, so a PR can't excuse its own failures.
rerun-unknown re-runs unknown pytest failures; one that passes is flaky.
Measuring recall before you rely on it
Set shadow: 10% on the select step. A sampled run still runs the full suite
while siftwise stores what it would have selected, then checks every failure against
it. Each miss gets a cause: new_test, flaky_history,
config_gap (with a suggested [[depends]] rule to review),
no_link or unknown. siftwise report shows recall over
time, the selective-only figure always next to the overall one.
Try it#
You need Docker, git and uv. The commands are bash; on Windows, use Git Bash or WSL. The quickstart takes about five minutes, and the project's CI runs it on every change.
Install the CLI
pip install siftwise                # the light CLI: select, record, triage, report, rollup
pip install 'siftwise[server]'      # plus the API server
pip install 'siftwise[mcp]'         # plus siftwise mcp, for coding agents
Start the server (Docker Compose)
The compose file runs the published image,
ghcr.io/pramodbasavarajmenasi/siftwise:0.1.0, with Postgres 16. The API token is a
shared secret you choose; it goes in .env:
git clone https://github.com/PramodBasavarajMenasi/siftwise.git
cd siftwise
[ -f .env ] || echo "SIFTWISE_API_TOKEN=$(openssl rand -hex 32)" > .env
docker compose up -d --wait             # pulls the image, waits until both services are healthy
curl -fsS http://localhost:8000/healthz # {"status":"ok"}

uv tool install siftwise                # or: pip install siftwise
export SIFTWISE_API_TOKEN=$(sed -n 's/^SIFTWISE_API_TOKEN=//p' .env)
Without compose, run the image directly against your own Postgres:
docker run -d -p 8000:8000 -e SIFTWISE_API_TOKEN=... \
    -e SIFTWISE_DATABASE_URL=postgresql+psycopg://user:password@db-host:5432/siftwise \
    ghcr.io/pramodbasavarajmenasi/siftwise:0.1.0
Record a run, then select
The repo ships a small example project. Record its tests once, change a file, and ask what to run:
demo="$(mktemp -d)/shop" && cp -r examples/quickstart "$demo" && cd "$demo"
git init -q && git add -A && git commit -qm "A shop"
uv run pytest -q --junitxml=junit.xml
siftwise record junit.xml --repo demo/shop --branch main --main

echo "# reviewed the bulk discount" >> shop/cart.py && git commit -qam "Touch the cart"
siftwise select --repo demo/shop --base HEAD~1 > selected.sh
cat selected.sh                         # pytest tests/test_cart.py
uv run sh selected.sh
The command goes to stdout and a summary to stderr:
siftwise: python imports: 1 test file(s) import changed modules
siftwise: selective (2 of 4 known tests): 2 of 4 known tests selected
--json adds a reason per test; docker compose down stops the
server.
The GitHub Action
Add two secrets, SIFTWISE_URL and SIFTWISE_TOKEN, and check out with
fetch-depth: 0 so the base...head diff works. For a matrix, each leg
selects and records its own variant, and one rollup job runs after every leg:
name: CI
on:
  push:
    branches: [main]
  pull_request:
permissions:
  contents: read
  actions: read
  pull-requests: write
jobs:
  test:
    strategy:
      matrix:
        os: [ubuntu-latest, macos-latest]
        python: ["3.11", "3.12"]
    runs-on: ${{ matrix.os }}
    steps:
      - uses: actions/checkout@v7
        with:
          fetch-depth: 0
      - uses: actions/setup-python@v7
        with:
          python-version: ${{ matrix.python }}
      - run: pip install -r requirements.txt   # your install step

      - id: siftwise
        uses: PramodBasavarajMenasi/siftwise/actions/select@main
        with:
          server-url: ${{ secrets.SIFTWISE_URL }}
          token: ${{ secrets.SIFTWISE_TOKEN }}
          comment: ${{ strategy.job-index == 0 }}   # one leg comments, or they race

      - name: Tests
        env:
          MODE: ${{ steps.siftwise.outputs.mode }}
          COMMAND: ${{ steps.siftwise.outputs.command }}
          JUNIT_DIR: ${{ steps.siftwise.outputs.junit-dir }}
        run: |
          if [ "$MODE" = selective ]; then
            # Shell-quoted by siftwise; each pytest command writes its own report to JUNIT_DIR.
            if [ -n "$COMMAND" ]; then eval "$COMMAND"; else echo "No tests affected."; fi
          else
            pytest --junitxml="$JUNIT_DIR/full.xml"   # your normal full suite
          fi

      - if: always()
        uses: PramodBasavarajMenasi/siftwise/actions/record@main
        with:
          server-url: ${{ secrets.SIFTWISE_URL }}
          token: ${{ secrets.SIFTWISE_TOKEN }}
          variant: ${{ matrix.os }}-py${{ matrix.python }}

  siftwise-rollup:
    needs: test
    if: always()
    runs-on: ubuntu-latest
    steps:
      - uses: PramodBasavarajMenasi/siftwise/actions/rollup@main
        with:
          server-url: ${{ secrets.SIFTWISE_URL }}
          token: ${{ secrets.SIFTWISE_TOKEN }}
Never use these actions with pull_request_target, which runs a fork's code with
your secrets; use pull_request. Pin @v0.1.0 or a commit SHA instead
of @main for reproducible CI. In a single job, leave out the rollup job:
record triages on its own.
MCP for coding agents (tested with Claude Code)
Install the CLI with the mcp extra, then register it. The agent starts the MCP
server in its working directory, so open the agent in the repository:
uv tool install 'siftwise[mcp]'  # or: pip install 'siftwise[mcp]'
claude mcp add siftwise --env SIFTWISE_SERVER=https://siftwise.example.com \
    --env SIFTWISE_API_TOKEN=your-token -- siftwise mcp
Or commit a project .mcp.json, which expands ${VAR} from your
environment, so the token itself stays out of the repo:
{
  "mcpServers": {
    "siftwise": {
      "command": "siftwise",
      "args": ["mcp"],
      "env": {
        "SIFTWISE_SERVER": "https://siftwise.example.com",
        "SIFTWISE_API_TOKEN": "${SIFTWISE_API_TOKEN}"
      }
    }
  }
}
Then tell the agent when to use it, in CLAUDE.md or AGENTS.md:
Before running tests, call the siftwise `select_tests` tool and run the command it returns.
When tests fail, call `triage_failure` before fixing anything: fix `new_regression` failures,
re-run `flaky` ones, and leave `pre_existing` ones (already failing on main).
The README also has configs for Codex and Cursor (untested so far; Claude Code is the tested client).
Evidence#
These are replays of real CI history with no peeking: for each target run, history is rebuilt only from runs before it, and import graphs are built at that commit. The repos were picked for having JUnit artifacts and real failures, not for flattering results. The method is in the eval methodology; every number below is in eval results.
Selection replays
| Repo | Failures caught | Test time skipped |
|---|---|---|
| RDFLib/rdflib Python, ~18,000 tests |
2,049 of 2,050 in 39 failing PRs; 140 of 141 in selective runs | 10.4% on the 10 most recent PRs; 0.6% over 19 main commits |
| agent-substrate/substrate Go, ~9,000 tests |
2,043 of 2,044 in 72 failing PRs; 38 of 39 in selective runs, with two declared rules | 5.1% on PR runs; 13.9% over 40 main commits, with both rules |
| quantumlib/Cirq Python monorepo, 9 packages |
Not measurable: JUnit only from main, which never failed | 37.9% over 132 merged PRs |
| ipfs/kubo Go, ~4,100 tests, week-2 code |
19 of 19 in failing PRs | 30.7% over 20 main commits replayed as PRs; 0% on recent PRs |
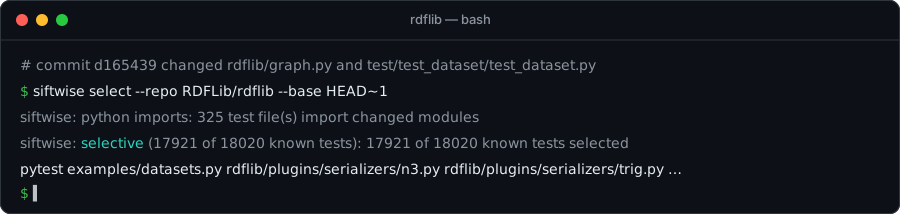
rdflib/graph.py reaches
325 test files through the import graph, so 17,921 of 18,020 known tests run. That's correct
for this codebase.The caveats matter as much:
- rdflib: failures cluster (one bad change can fail hundreds of tests), so
140 of 141 in the 18 selective runs is the more honest figure. The miss,
test_service_with_bound_solutions, calls a remote SPARQL service and had failed in 2 earlier unrelated runs: it's flaky. Its 10.4% comes from two lint-only PRs. - substrate: without declared rules, selective runs caught only 26 of 38;
the misses were end-to-end suites no import edge reaches. Two
[[depends]]rules close the gap at the cost of most of the savings (5.1% skipped vs 19.5%). Only 8 days of history. - Cirq measures savings, not safety: there are no PR test results. Before a fix, a nearly empty import graph made it claim an unsafe 59.8%.
- kubo used older (week-2) code, and every failing run fell back to the full suite, so selective recall is unmeasured there.
Triage eval
Every run with failures was triaged by the production engine as of just before it, then scored against proxy labels from what happened afterwards.
- Regressions called flaky, the worst error: 0 on rdflib; 5 of 406 labelled regressions on substrate, all on tests with earlier same-commit flakes; 4 are likely label noise.
new_regressionheld up: 319 of 319 labelled substrate failures, and 10 of 11 rdflib fix episodes with a known diff.pre_existing: 2,092 of 2,092 on substrate, including 759 of 759 called at medium confidence after a single failing main run.flakyprecision is mostly by construction: 678 of 683 flaky verdicts come from a pass of the same commit, the same fact the flaky label uses.- Unknown when unsure: 12.6% of substrate's failures and 14% of rdflib's, mostly runs whose diff was never recorded.
Caveats: the labels are proxies that partly share evidence with the rules, and episodes are
few (12 on rdflib, 34 on substrate), so treat percentages as counts. Blind spot: on rdflib,
where every change links to every test and CI never re-runs a commit, the remote-service tests
were called new_regression 12 times out of 13.
Shadow mode
No live shadow-mode recall numbers are published yet; that comes after launch. The mechanism is tested end to end: the project's action-e2e.yml runs all three actions against a real server on every push and PR, including a shadow run with a miss. The screenshot is that comment; the tests are the workflow's fixtures, not a real project's.
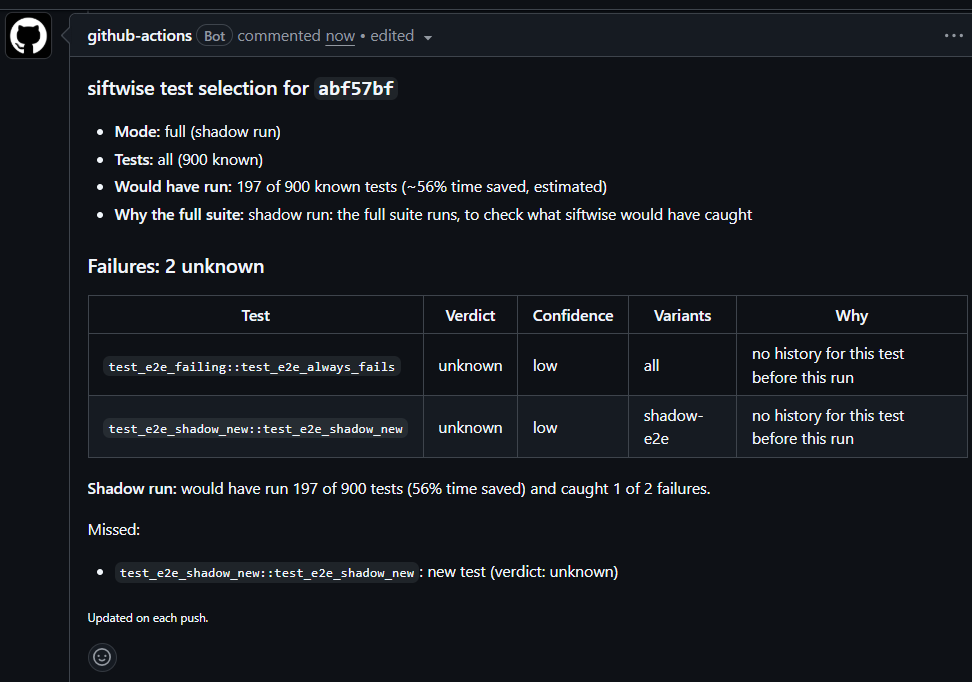
Live numbers will be raw counts: failures are rare on healthy repos, and zero misses in n failures only bounds the miss rate below about 3/n at 95%.
Performance
Measured on 2026-10-19 on a Windows laptop, Postgres 16 in Docker; results identical before and after.
| Path | Before | After |
|---|---|---|
| Triage of rdflib's widest CI run attempt (22 variants) | 1,032 ms, 180 queries | 220 ms, 12 queries |
Selection inside /select, rdflib, a one-file change | 605 ms | 237 ms |
| Shadow comparison, 1 / 5 / 20 variants (synthetic) | 27 / 75 / 255 queries | 27 / 27 / 27 |
| Ingest of a 9,891-result rdflib upload | ~2.2 s | ~1.25 s |
/select takes about 0.4 s on rdflib's 18,000 tests (0.3–1.4 s across the
measured changes). Not everything
is fast: the repo-wide stats rollup takes 119 s on rdflib, and that wasn't changed.
Limits, and what the numbers don't prove#
siftwise is alpha: APIs and the schema may change before 1.0. Known limits:
- One API token per server, with read and write access to every repo on it; no per-repo or read-only tokens.
- Merge-queue (
merge_group), scheduled and manual runs always run the full suite: there's no diff base. - Java tests are recorded but always run in full. Jest selection needs file paths in the
JUnit and isn't evaluated on a real repo.
rerun-unknownre-runs pytest only. - The Action is tested on Linux runners only, and the server image is linux/amd64 only.
- Renamed or moved tests start with no history.
And what the evals don't show:
- recall on repos with dynamic dependencies the graphs can't see (plugins loaded by name
from outside the repo, data-driven tests), beyond what
[[depends]]covers; - behaviour on languages other than Python and Go;
- live recall: every number here replays past CI history of four repos;
- that flaky verdicts generalise, since most re-read the label's own evidence.
Roadmap and contributing#
- Done in 0.1.0: everything above.
- Next: a demo, this launch write-up, and an arm64 server image.
- After launch: live dogfooding, with shadow mode on siftwise's own CI and a hosted server, and published live recall numbers.
Issues and pull requests are welcome: see CONTRIBUTING.md for the dev setup and PR checklist, and ARCHITECTURE.md for how the pieces fit. Shadow-mode recall from your own CI is the evidence the replays can't provide. Report vulnerabilities privately, as SECURITY.md describes.
Links#
- Source: github.com/PramodBasavarajMenasi/siftwise
- PyPI: pypi.org/project/siftwise
- Server image (GHCR): ghcr.io/pramodbasavarajmenasi/siftwise
- Docs: README, Architecture, Eval results, Eval methodology, Changelog